NVIDIA Dynamo vs KServe: Which Layer Should Own Your LLM Inference?
Cache-aware routing, prefill/decode disaggregation and autoscaling compared, and how to choose per model pool
Cache-aware routing, prefill/decode disaggregation and autoscaling compared, and how to choose per model pool
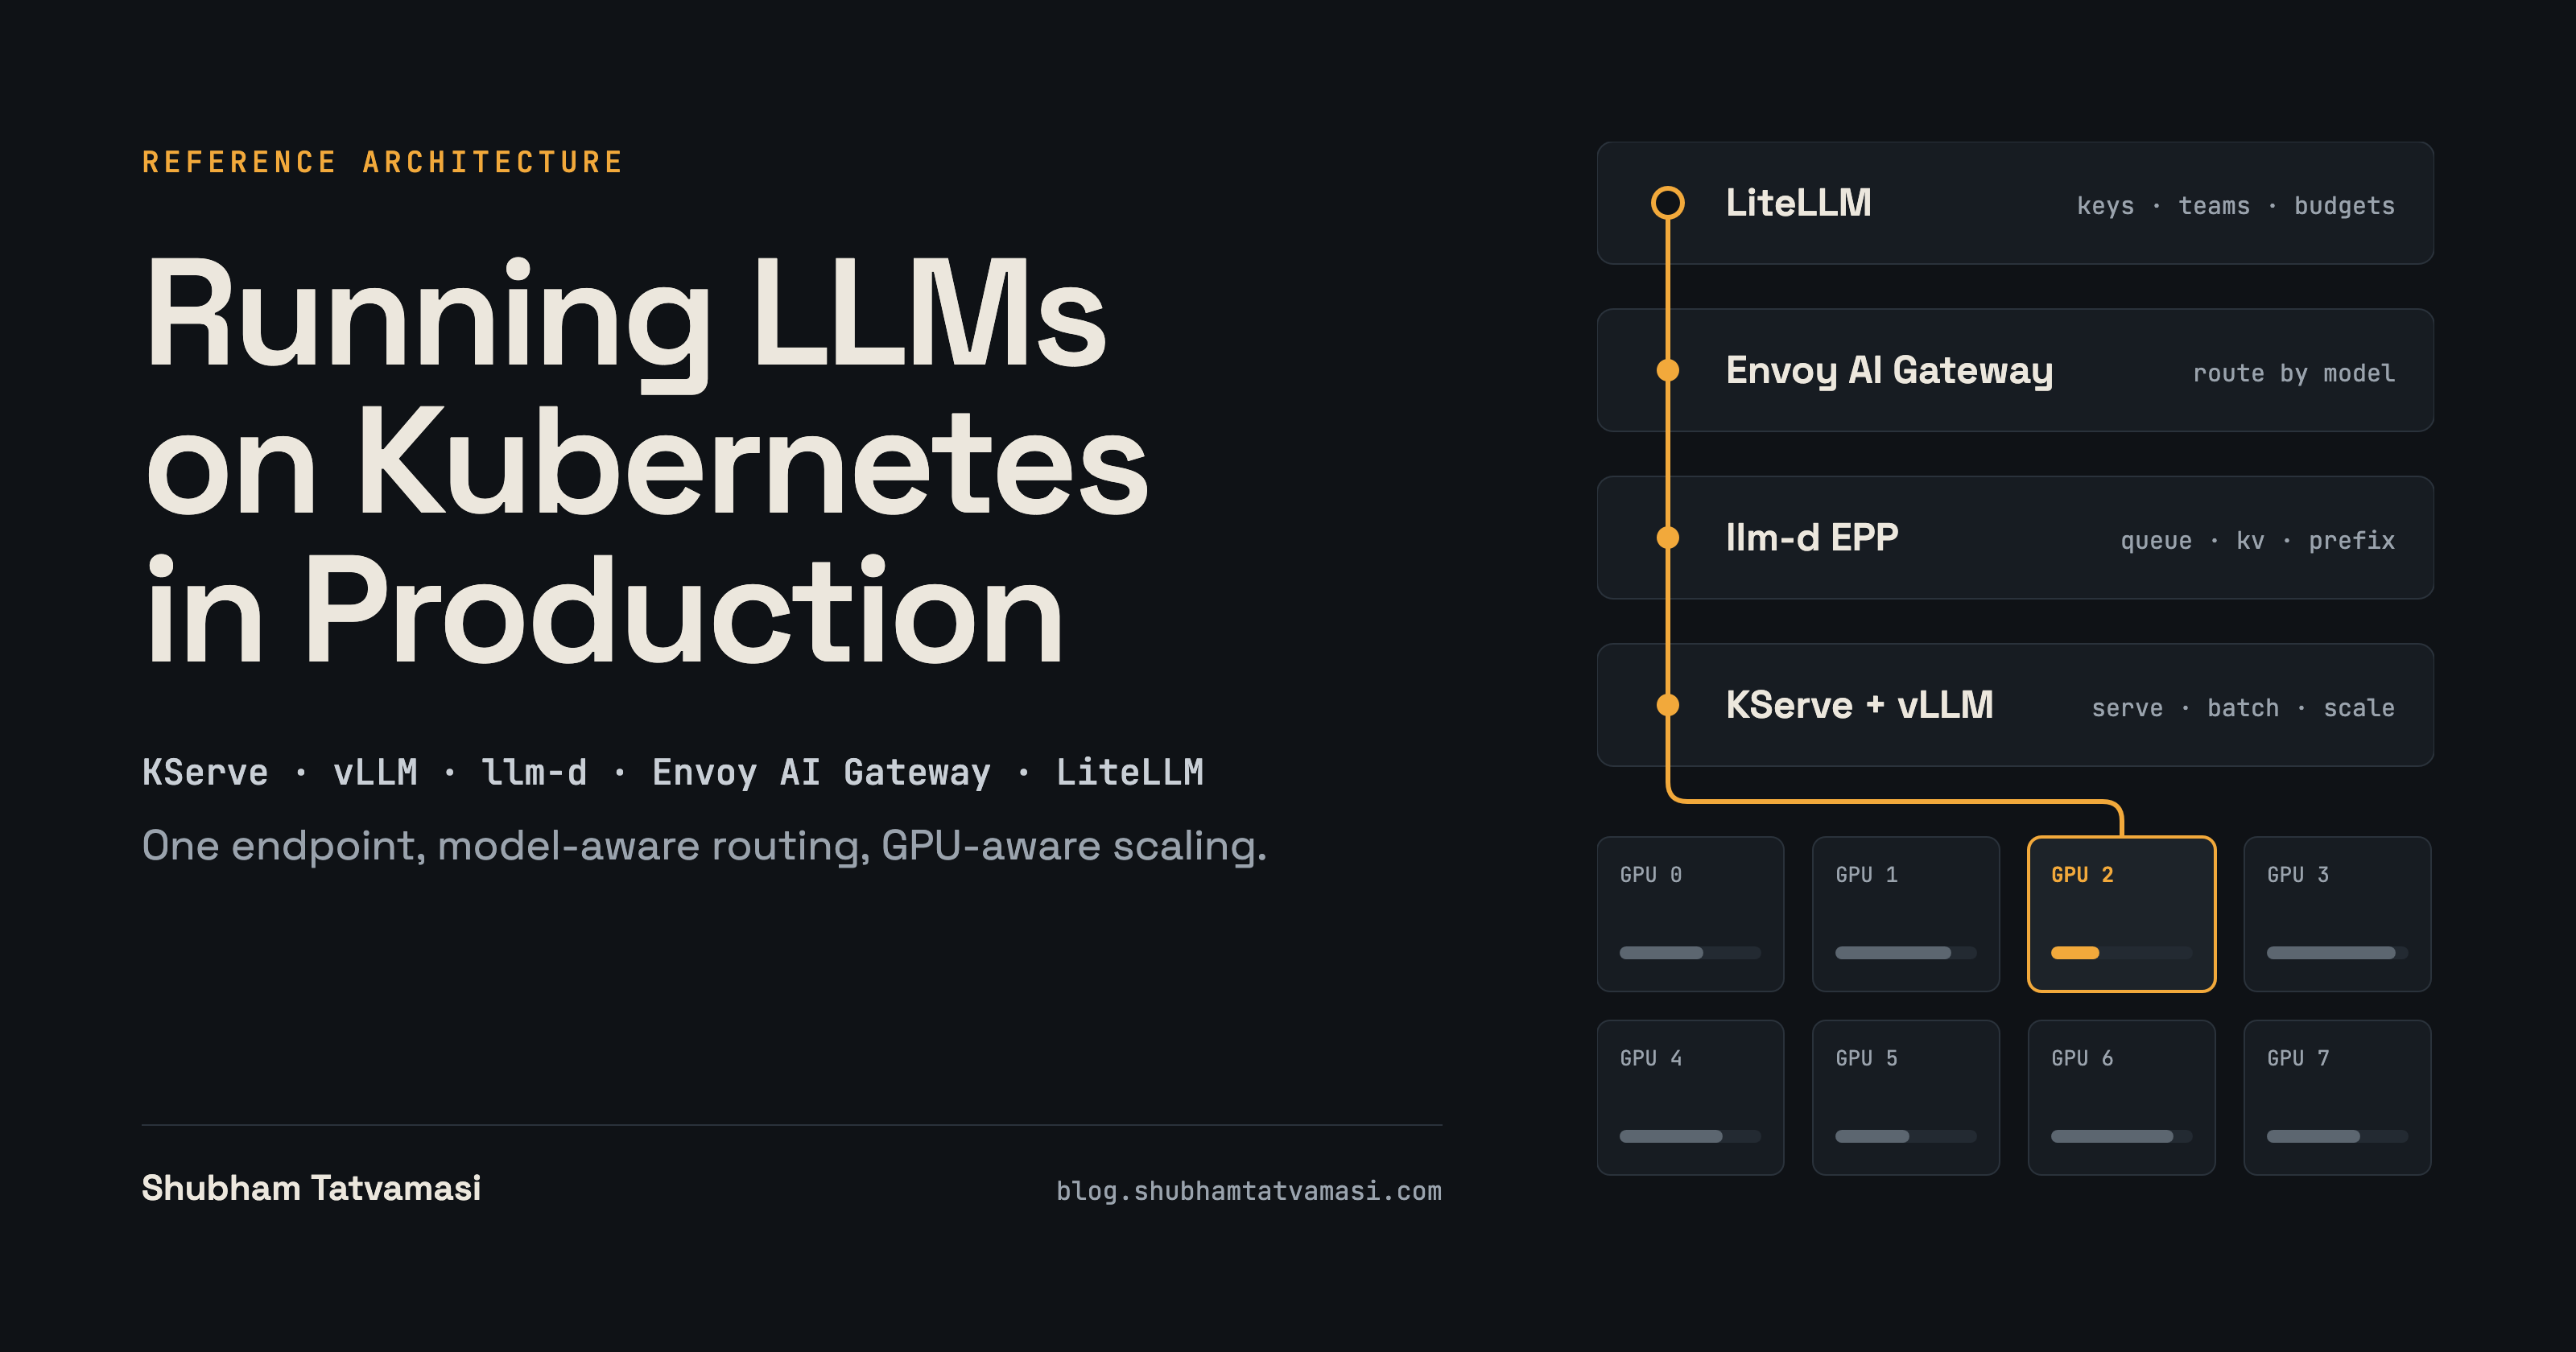
One OpenAI-compatible endpoint, model-aware routing, GPU-aware scheduling, and scaling driven by inference pressure, not CPU