Inside NVIDIA Dynamo: A Deep Technical Tour of the Datacenter-Scale Inference Stack
Disaggregated prefill/decode, KV-aware routing, NIXL, KVBM, the SLA Planner, and the Kubernetes machinery behind them
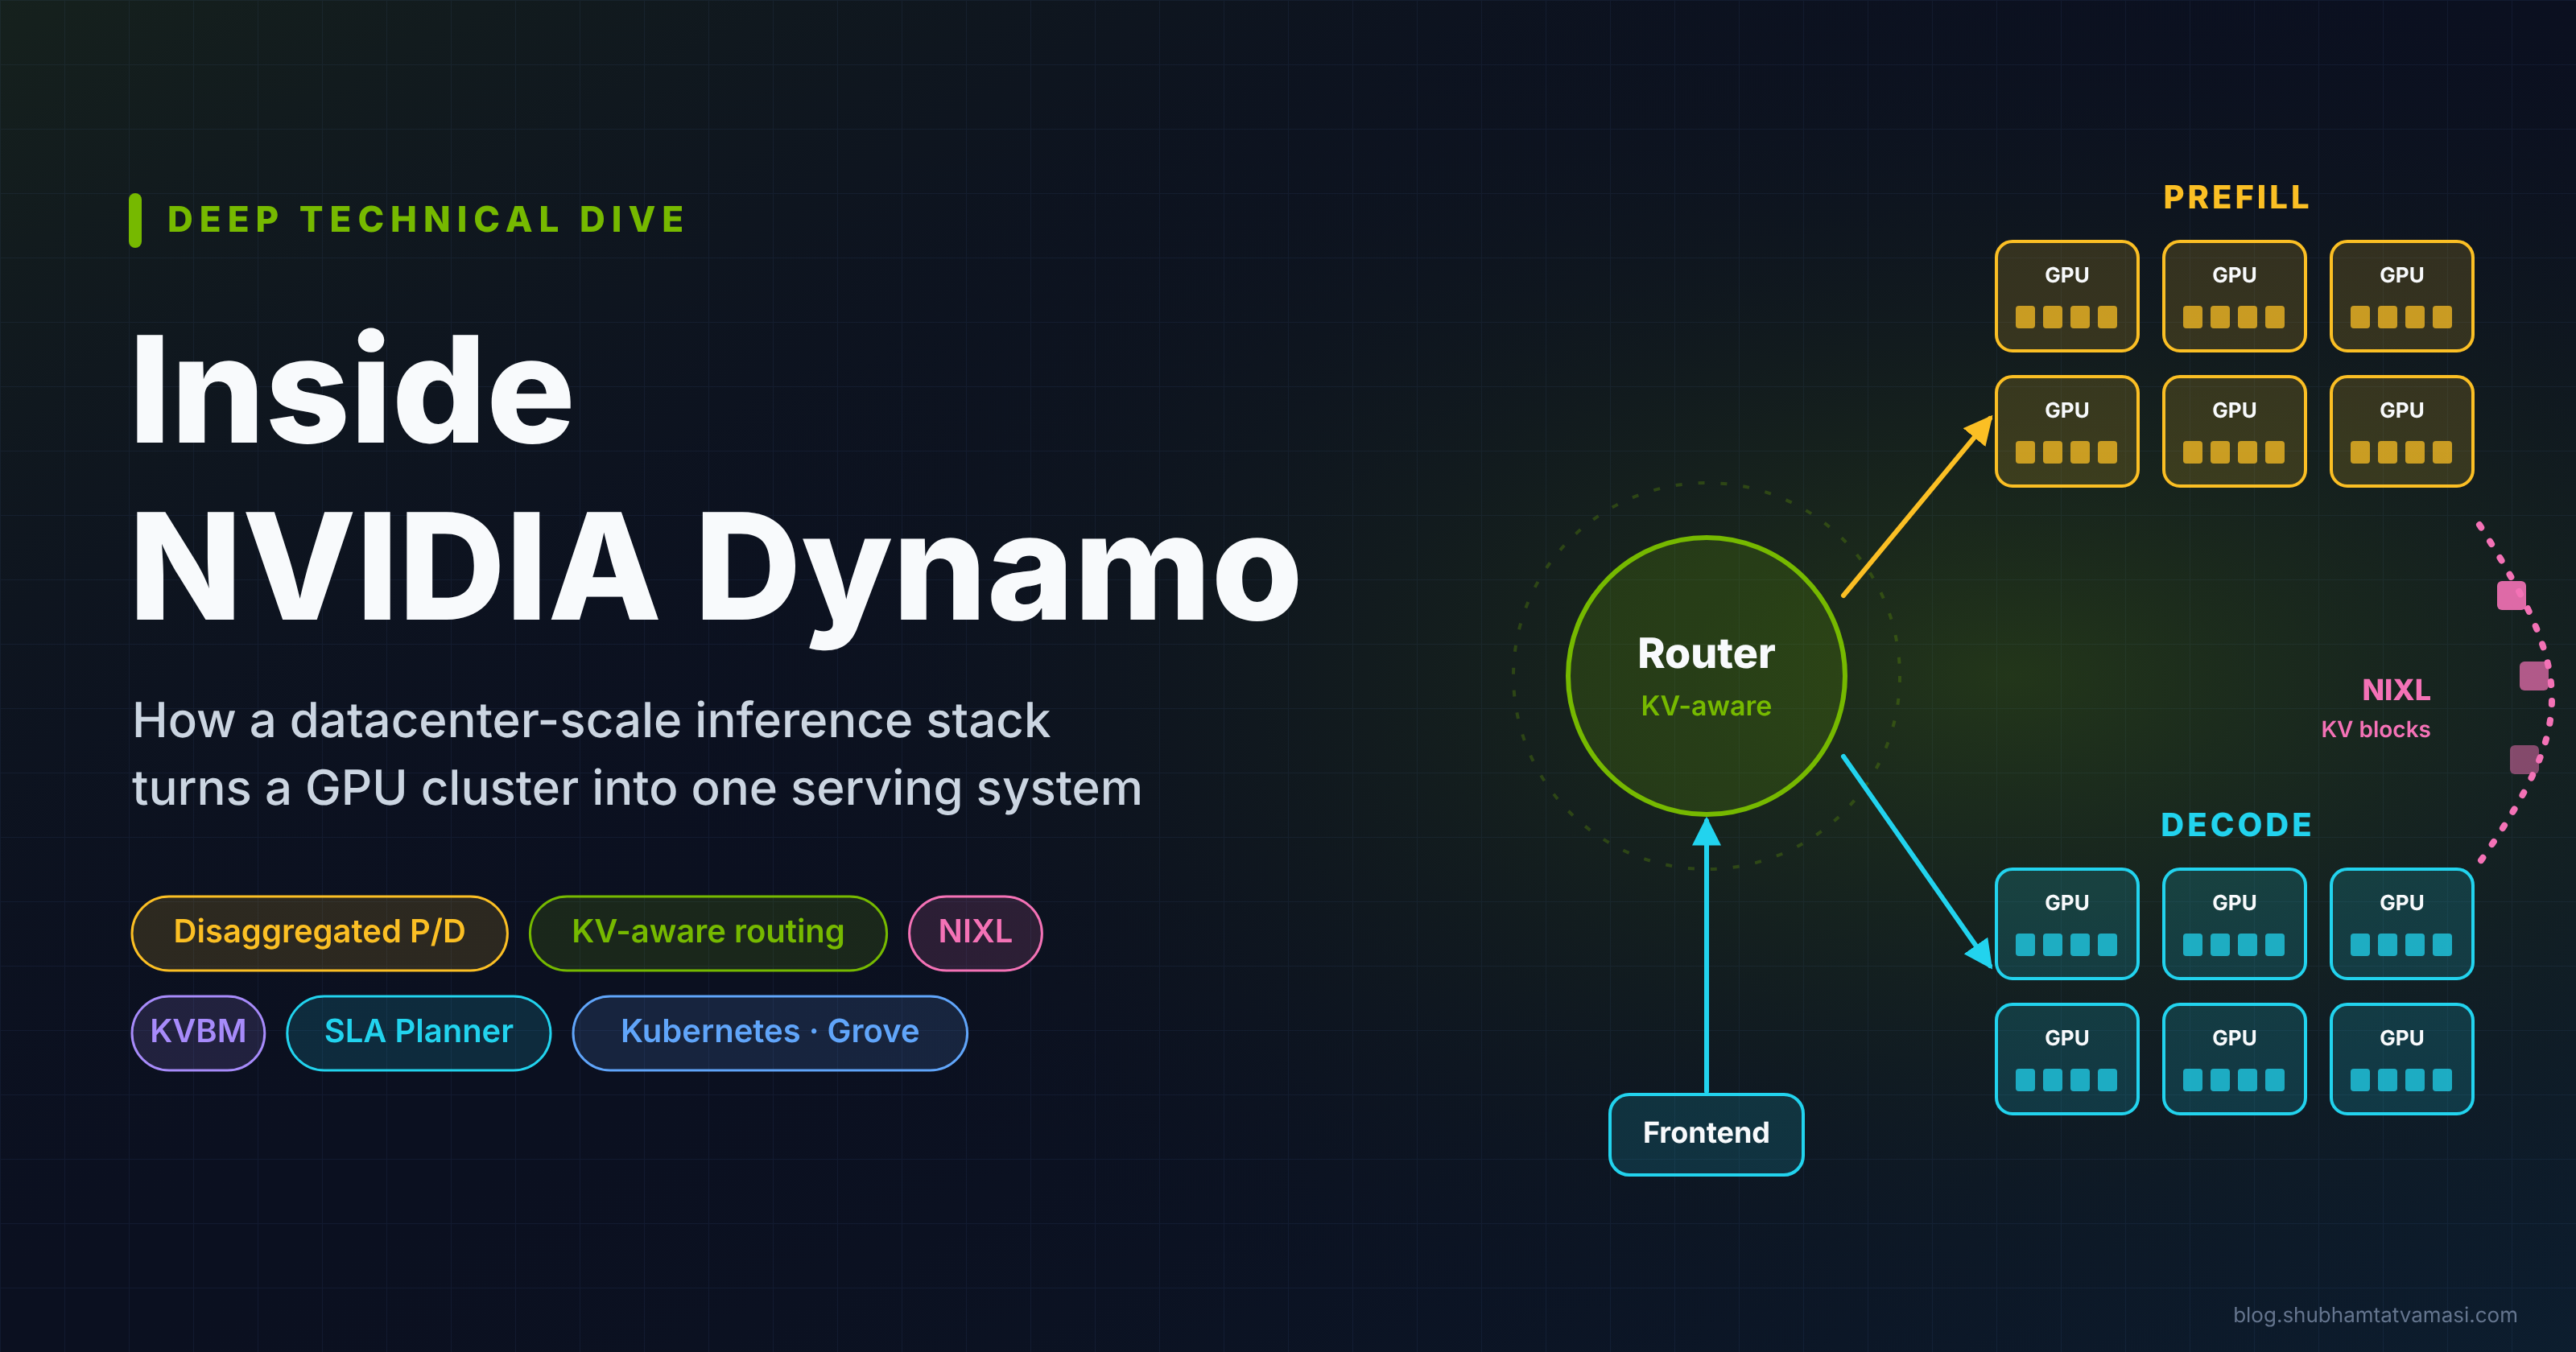
Disaggregated prefill/decode, KV-aware routing, NIXL, KVBM, the SLA Planner, and the Kubernetes machinery behind them
Queues, gang scheduling, fractional GPUs and topology-aware placement: how NVIDIA’s open-source scheduler shares GPUs